Partners
NVIDIA Nemotron
Nemotron plans answers, finds passages, screens deep searches, guards what's public, and stands in for every OpenAI agent role.
konkyo.xyz/made-with/nvidia
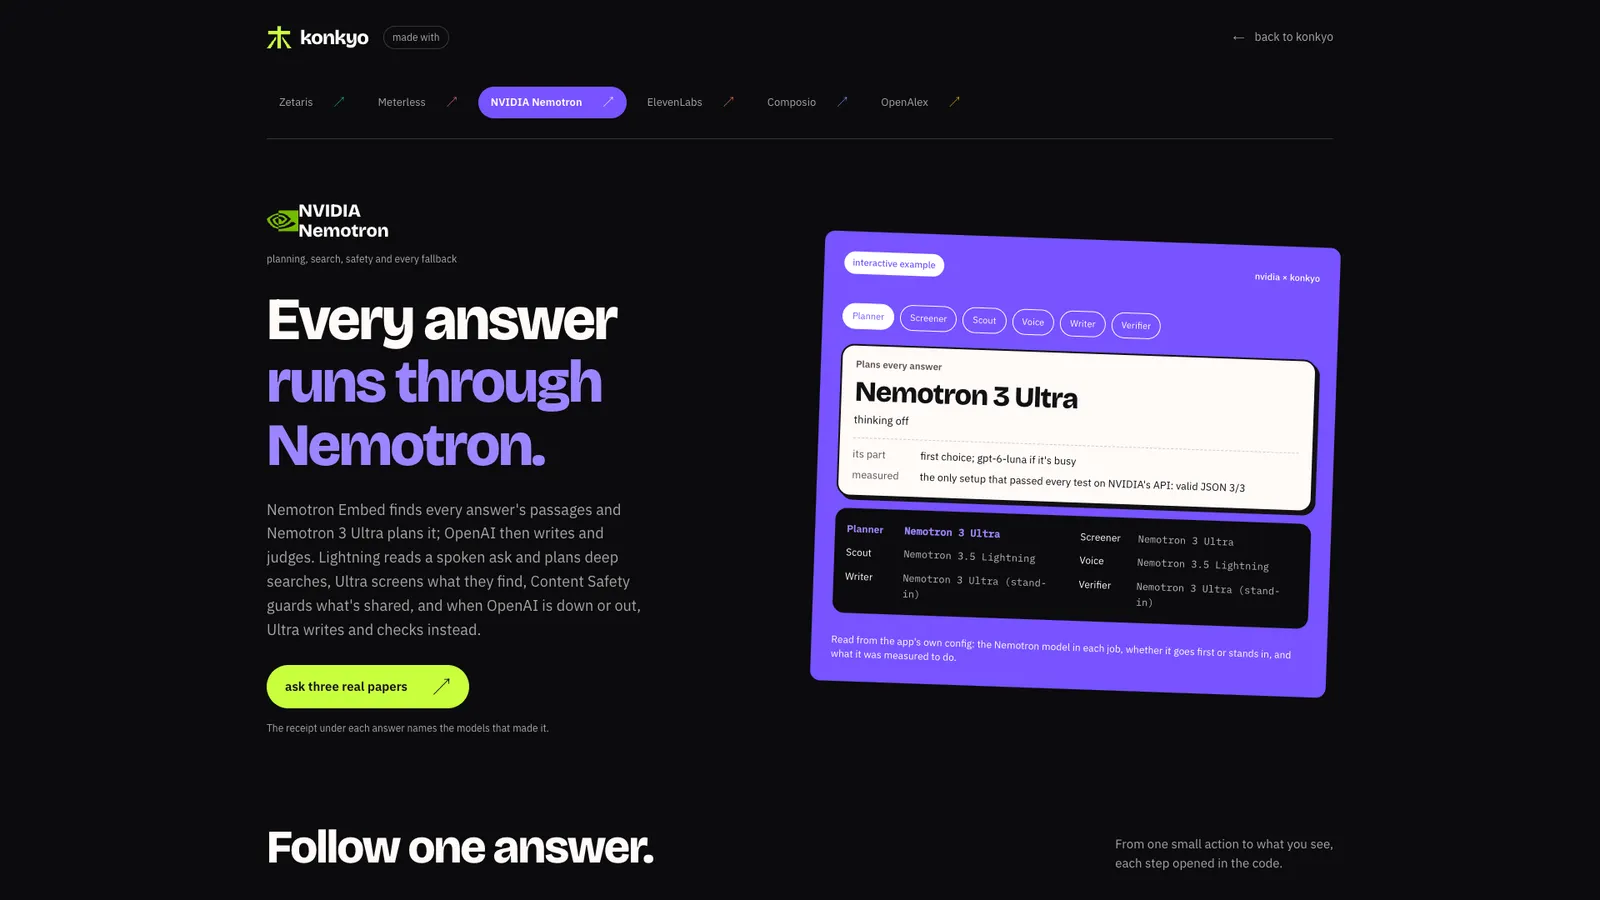
Konkyo calls two providers from one place (packages/models): OpenAI's gpt-6-luna writes and
judges (the Writer, Verifier, Analyst, Tutor and Grader), and Nemotron on NVIDIA's API does the
rest, apart from deep search's web search (OpenAI's gpt-5-nano), and stands in for those roles
whenever OpenAI is down or out of credit.
| Model | What it does |
|---|---|
| Nemotron 3.5 Embed | Finds the passages: every passage embedded as a passage and every question as a query, at 1536 of its 2048 dimensions, beside Postgres full-text search |
| Nemotron 3 Ultra (550B, 55B active) | Plans each answer (OpenAI stands in while it's busy), screens deep-search finds in Markovian steps, and is the fallback for every OpenAI agent role |
| Nemotron 3.5 Lightning (30B, 3B active) | Plans deep searches, reads a spoken ask no rule placed, summarises each file as it's read |
| Nemotron 3.5 Content Safety | Checks questions asked in a public space, public profiles, and every article before it's published |
| Nemotron 3.5 Super VL | A reserve for the Writer, Analyst and Tutor |
Inside the free tier
- Thinking is a switch per role, sent through Nemotron's chat template (
enable_thinking,low_effort,reasoning_budget). - A rate limit per model in each process: the web app's and the worker's shares add up to NVIDIA's ~40 a minute.
- Hedged requests: a call that runs past its usual time is asked again, and the first answer wins.
- Busy models wait their turn: one that answers 429 or stalls is tried last for the next minute.
Your own GPUs instead
MODEL_BASE_URL sends the Nemotron calls to a self-hosted NVIDIA NIM serving the same model ids.